

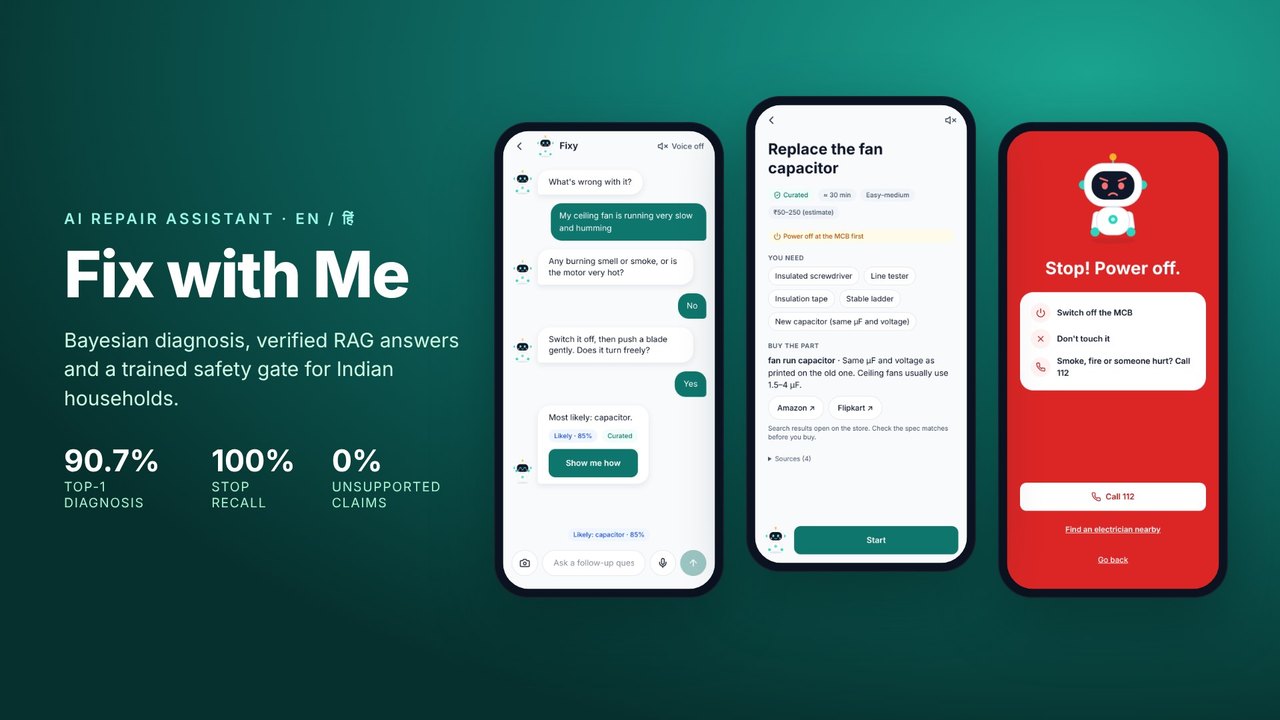
Fix with Me
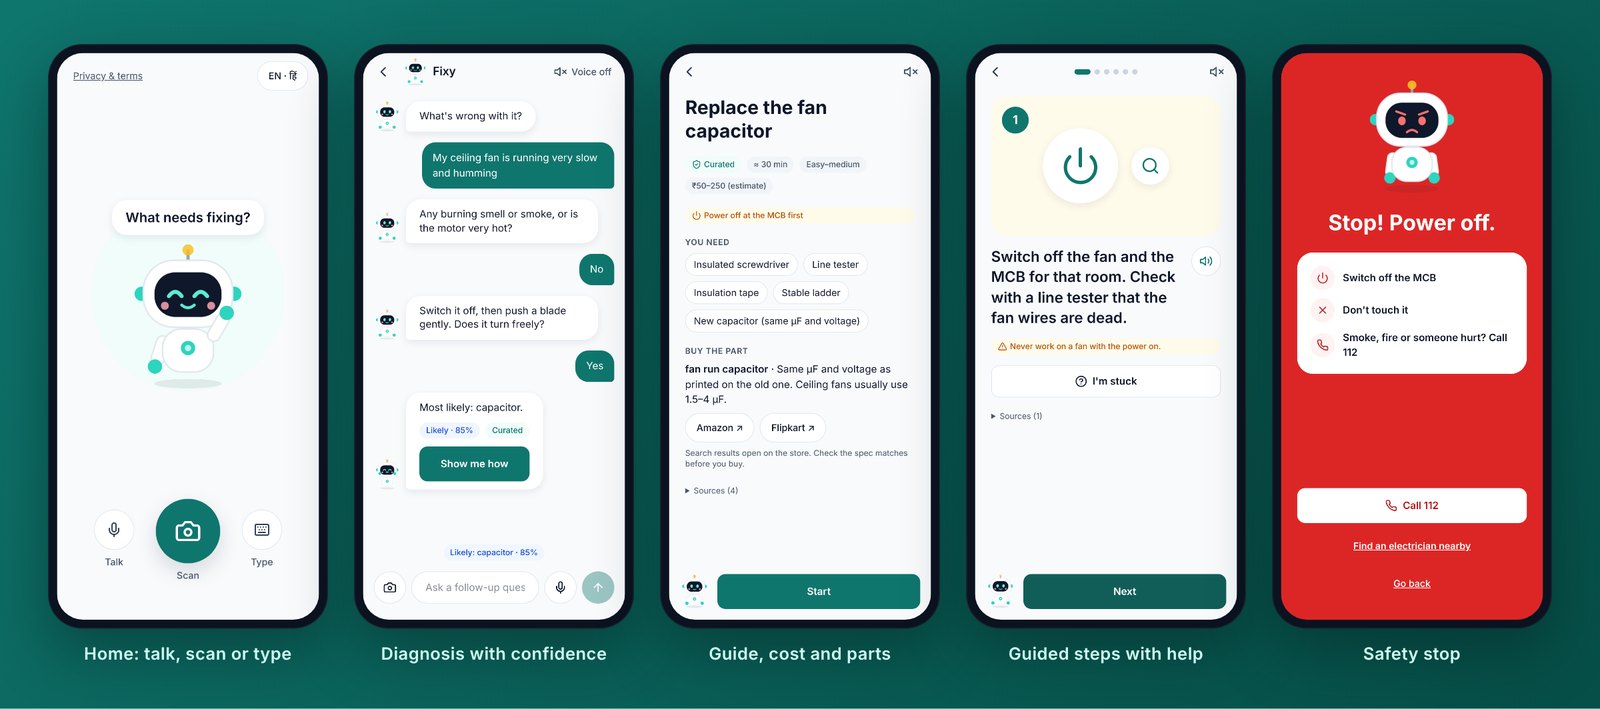
Users type, talk or snap a photo of what is broken. A Bayesian diagnosis engine over a curated knowledge base picks the most informative next question, reaching 90.7% top-1 accuracy on a 94-case benchmark versus 81.3% for plain Gemini. Follow-up questions run through hybrid RAG on Supabase (pgvector + PGroonga, Reciprocal Rank Fusion, 100% recall@5) with per-claim verification by Gemma, cutting unsupported claims from 34% to 0%. A trained TF-IDF + logistic regression safety classifier (3.8K examples, 0.68 MB pure-Python runtime, about 0.2 ms per message) lifts hazard recall from 67.2% to 89.1%.
diagnosis
claims
recall
in CI
Web app on Cloudflare Workers, API on Render’s free tier: the first answer can take about a minute while the API wakes up.